

Thesis. The standard argument against long-horizon agents is multiplicative: if each of n steps succeeds independently with probability p, the sequence succeeds with probability pⁿ, and at five hundred steps even 0.99 per step leaves you at two-thirds of one per cent. The argument is arithmetically correct and empirically wrong, because the steps are neither independent nor separately decided. When a model emits a plan as a program, hundreds of actions are generated by a handful of statements, and the number of decisions that can go wrong is not the number of actions taken. The measured failure data bears this out: in the strongest models, execution errors fall to two-hundredths of a mistake per task while planning errors remain an order of magnitude larger. Long plans do not unravel; they are built on a premise that was wrong before the first action was taken, and then carried out correctly. That is a different disease, with different treatments, and the treatments the compounding story recommends — per-step reliability engineering, more verification passes, more retries — address the part that already works.
Abstract. I take the compounding-error argument seriously enough to test it against a benchmark built for the purpose: a structured virtual world in which models must emit an entire executable plan, hundreds to thousands of actions long, in a single shot with no environmental feedback, after solving a numerical optimisation over combat statistics to determine what equipment the plan needs. Across two dozen models, the error data separates cleanly into failures of the high-level plan and failures of its execution, and the two behave very differently as capability rises: execution error collapses toward zero while planning error persists. I then look at what does break plans, which turns out to be two things that do not lengthen them at all — requiring the agent to bootstrap prerequisites it does not start with, and inserting plausible options that cannot actually be built. On the hardest configuration, three of the five leading models solve nothing. I examine two proposed remedies against the same data: repeated sampling, which does not close the gap between a weak proposal distribution and a strong one even at two hundred attempts, and multi-agent decomposition, where the more elaborate of two architectures performed worse than the bare model it was built on. I close with what the benchmark deliberately does not test, and what an honest claim about a long-horizon agent would have to contain. Two figures.
I. The argument everyone makes
Here is the case against long-horizon agents, in the form it usually takes.
An agent taking n steps, each succeeding independently with probability p, completes the sequence with probability pⁿ. Put in numbers: at 99% per step and five hundred steps, 0.99⁵⁰⁰ ≈ 0.0066. Two-thirds of one per cent. Push per-step reliability to 99.9% and five hundred steps still leaves you at 61%. The conclusion writes itself: long-horizon autonomy requires per-step reliability so extreme that it is not obviously reachable, and everything else — better prompts, bigger models, more tools — is rearranging deck chairs.
The arithmetic is right. The model is wrong, and it is worth being exact about why, because the error is not a quibble. It points at the wrong repair.
II. Plans are programs, not sequences of coin flips
Two assumptions are buried in pⁿ, and both fail.
The steps are not independently decided. Consider how a plan of a thousand actions is actually produced. In the benchmark I will draw on throughout, the model is required to emit its plan as Python, and is permitted to use loops for repeated resource acquisition — gather this ore forty times, fight that monster twelve times. So a thousand actions are generated by perhaps thirty statements. The agent made thirty decisions, not a thousand. If each of those is 99% reliable, the plan succeeds with probability 0.99³⁰ ≈ 0.74, which is a very different number and one that matches observed performance far better than 0.0066.
This is not a trick of the benchmark’s design. It is what structure is. A plan with no repeated substructure, no reusable subroutine, no quantifier over a set of similar objects, is not a plan — it is a list. The whole point of hierarchical planning is that the number of things you have to get right is much smaller than the number of things you do.
The errors are not independent. pⁿ requires that a failure at step 400 carries no information about the probability of failure at step 401. In practice failures cluster: they come from a single mistaken belief, expressed once and relied on repeatedly. The agent that has mis-estimated how much iron it needs will be wrong every time it counts iron. The agent that has misread a coordinate will be wrong at every visit to that location. Correlated errors have a completely different failure profile from independent ones — fewer, larger, and traceable to a source.
Which gives a prediction. If errors were independent, we would expect long plans to fail late, diffusely, and at rates that improve smoothly with per-step reliability. If the correlated-decision picture is right, we would expect long plans to fail early, at the point where premises are set, and for improvement in models to show up as a collapse in the execution error rate while the planning error rate proves stubborn.
That prediction is testable, and it has been tested.
III. What the measurement looks like
The environment is a grid world of seventy locations containing resource nodes, workshops and monsters — twenty-five monsters, seventeen resource types, two hundred and eight distinct items — with all mechanics defined in data files rather than learned from folklore, which matters because it keeps the answers out of the pretraining corpus in a way that Minecraft, say, does not.
A task names a target: defeat this monster, or craft this item. The dependency structure is a directed acyclic graph of crafting and gathering requirements, sometimes many levels deep — mine ore, smelt it, use the bar in a recipe that also requires a drop from a monster that must itself be defeated first. Task difficulty is defined by the number of missing items plus the summed cost of acquiring them, and runs from 2 to 97 across a dataset of 844 tasks, of which 180 were used, spread across nine difficulty brackets.
The combat tasks add a numerical layer that has to be solved before any action is taken. The agent must compute the minimal set of equipment that guarantees victory — minimal in a strict set-theoretic sense: the character wins with the set, and loses if any single item is removed. Getting there requires reasoning over four elemental damage types and their matching resistances, percentage-based amplifications, hit points and raw attack, simulated through turn-based combat. This is not flavour text. It is a small combinatorial optimisation whose answer determines the entire remainder of the plan, and it must be produced up front.
Then the model emits the whole plan as code. No environment feedback. No observing what happened and adjusting. The drop rates are set to certainty, so the world is deterministic — the benchmark supports stochastic mode and does not use it here. The code is parsed, executed against the simulator, and scored two ways: a binary success, and a progress score reflecting valid intermediate accomplishments.
The design choices are worth pausing on, because they are what make the results interpretable. By removing feedback and randomness, the benchmark isolates planning from recovery. Whatever fails, fails because the plan was wrong, not because the world moved. That is a real limitation, which I will come back to, and it is also the only way to get a clean read on the question at hand.
IV. One task, end to end
Abstraction is cheap. Here is what a single task demands, in order.
The prompt names a monster and hands over the world: the character’s current level and equipment, the statistics of the target, the recipes, the resource nodes and their locations, the other monsters and what they drop. Somewhere between one and eleven thousand tokens of it.
First, a numerical optimisation the agent must complete before it moves. Which equipment set defeats this monster? Not any set — the minimal one, in the strict sense that removing any single item turns a win into a loss. Getting there means simulating turn-based combat over four elemental damage channels and their matching resistances, percentage amplifications, hit points and raw attack, and searching the space of admissible items for the smallest subset that survives the simulation. This answer determines everything downstream. If it is wrong by one resistance value, every subsequent step is wasted labour toward the wrong equipment.
Second, a traversal. For each item in that set that the character does not already hold, walk the crafting dependency graph to its leaves. Some branches end at a resource node — mine ore here, chop wood there. Some end at another monster, which must be defeated for a drop, which may itself require equipment the character does not yet have. Some end at a workshop where an intermediate must be smelted before it can be used. The graph is directed and acyclic and can be several levels deep.
Third, quantities. Each recipe consumes a specific number of each input, each input has its own recipe consuming its own inputs, and the totals multiply up the tree. This is where most low-level execution errors live: not in the shape of the plan but in the arithmetic hanging off it.
Fourth, geography. Every gather, craft and fight happens somewhere, and the coordinates are in the prompt. A misread location produces a plan that walks confidently to an empty square.
Fifth, the code. All of it, emitted as a single Python program, loops permitted for the repetitive parts, no feedback, no second look.
Now consider where an error is fatal. A wrong quantity at step 300 costs one wasted trip; the plan may still succeed. A misread coordinate costs one failed action. But a wrong answer at the first stage — the gear calculation, performed before anything happens — costs the entire task, and it costs it silently, because everything after it will be internally consistent and correctly executed. The agent will gather the right materials for the wrong equipment, craft it perfectly, equip it, walk to the monster and lose.
That asymmetry is the whole argument. The steps are cheap and recoverable. The premise is neither.
V. Where the errors actually are
Two error counts are reported per task: how many items were missing from the high-level plan, and how many low-level execution mistakes were made — wrong quantities, misused coordinates, redundant steps.
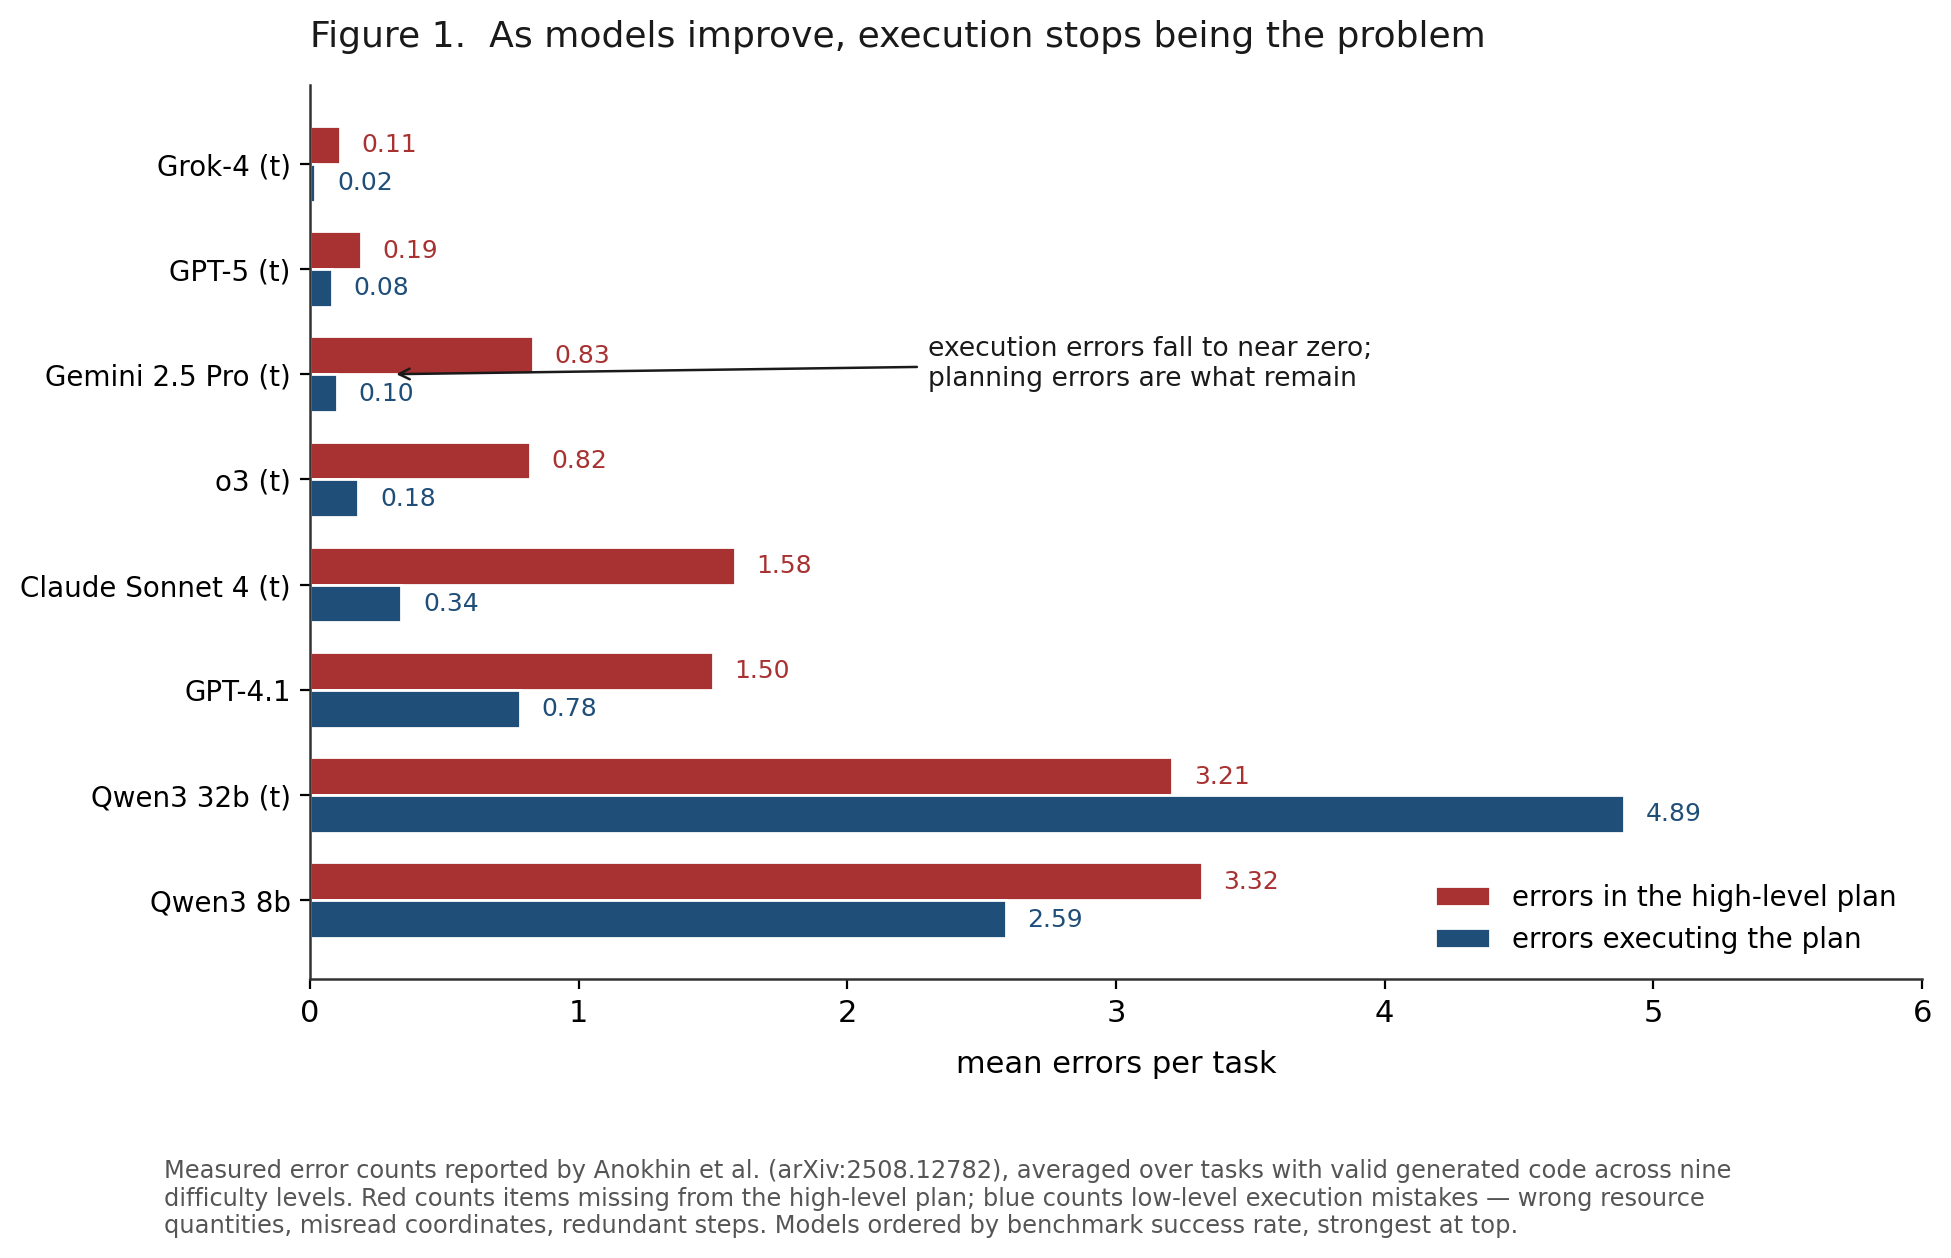
Figure 1. As models improve, execution stops being the problem. Mean errors per task, on tasks where the model produced valid code. At the weak end the two error types are comparable and both large. At the strong end they separate by an order of magnitude: the best model averages 0.11 planning errors and 0.02 execution errors per task. Execution is nearly solved. Planning is not.
Read the top of that chart carefully. The strongest model makes one execution mistake in every fifty tasks — across plans containing hundreds to thousands of actions. If you were told only that, and asked to predict the failure rate from compounding, you would predict near-perfect reliability. The observed failure rate on the same tasks is not near-perfect, and the residual is sitting in the other bar.
The failure attribution confirms it. For the strong reasoning models, failures concentrate in gear selection alone rather than gear selection plus execution: for one leading model, 29.4% of all tasks failed on gear selection with clean execution, against 15.6% that failed on both. Code formatting — the most mechanical possible failure — accounts for 0.6% in the best case, and the paper notes this as excellent instruction-following. It is. It is also the part that was never the bottleneck.
So the picture is not a thousand small slips accumulating. It is a handful of decisions taken before the plan begins, one of which is wrong, followed by a long, faithful, competent execution of a plan that could not have worked.
That distinction is everything, because a plan that reads beautifully and is executed flawlessly and loses the fight is exactly what “convincing rationalisation rather than a causally effective plan” looks like in the wild. The rationalisation is not sloppy. It is meticulous. It is just built on a gear calculation that was off by one resistance value.
VI. What actually breaks the plans
If length is not the enemy, what is?
Two modifications to the hardest tasks, neither of which makes the plans meaningfully longer.
The first is skill progression: instead of starting with professions already at the level required by the target item, the agent starts at level one in everything and must work out how to bootstrap. It is given the information — which resources give which experience, where they are — and must construct a sequence that raises its own capabilities to the point where the real task becomes possible. This is a prerequisite structure over the agent’s own competence rather than over materials.
The second is adversarial distractors: plausible, high-powered items are added to the world description, statistically indistinguishable from valid options, with their crafting recipes fully supplied — and with at least one required ingredient simply absent from the environment. They look like the obvious answer. They cannot be made.
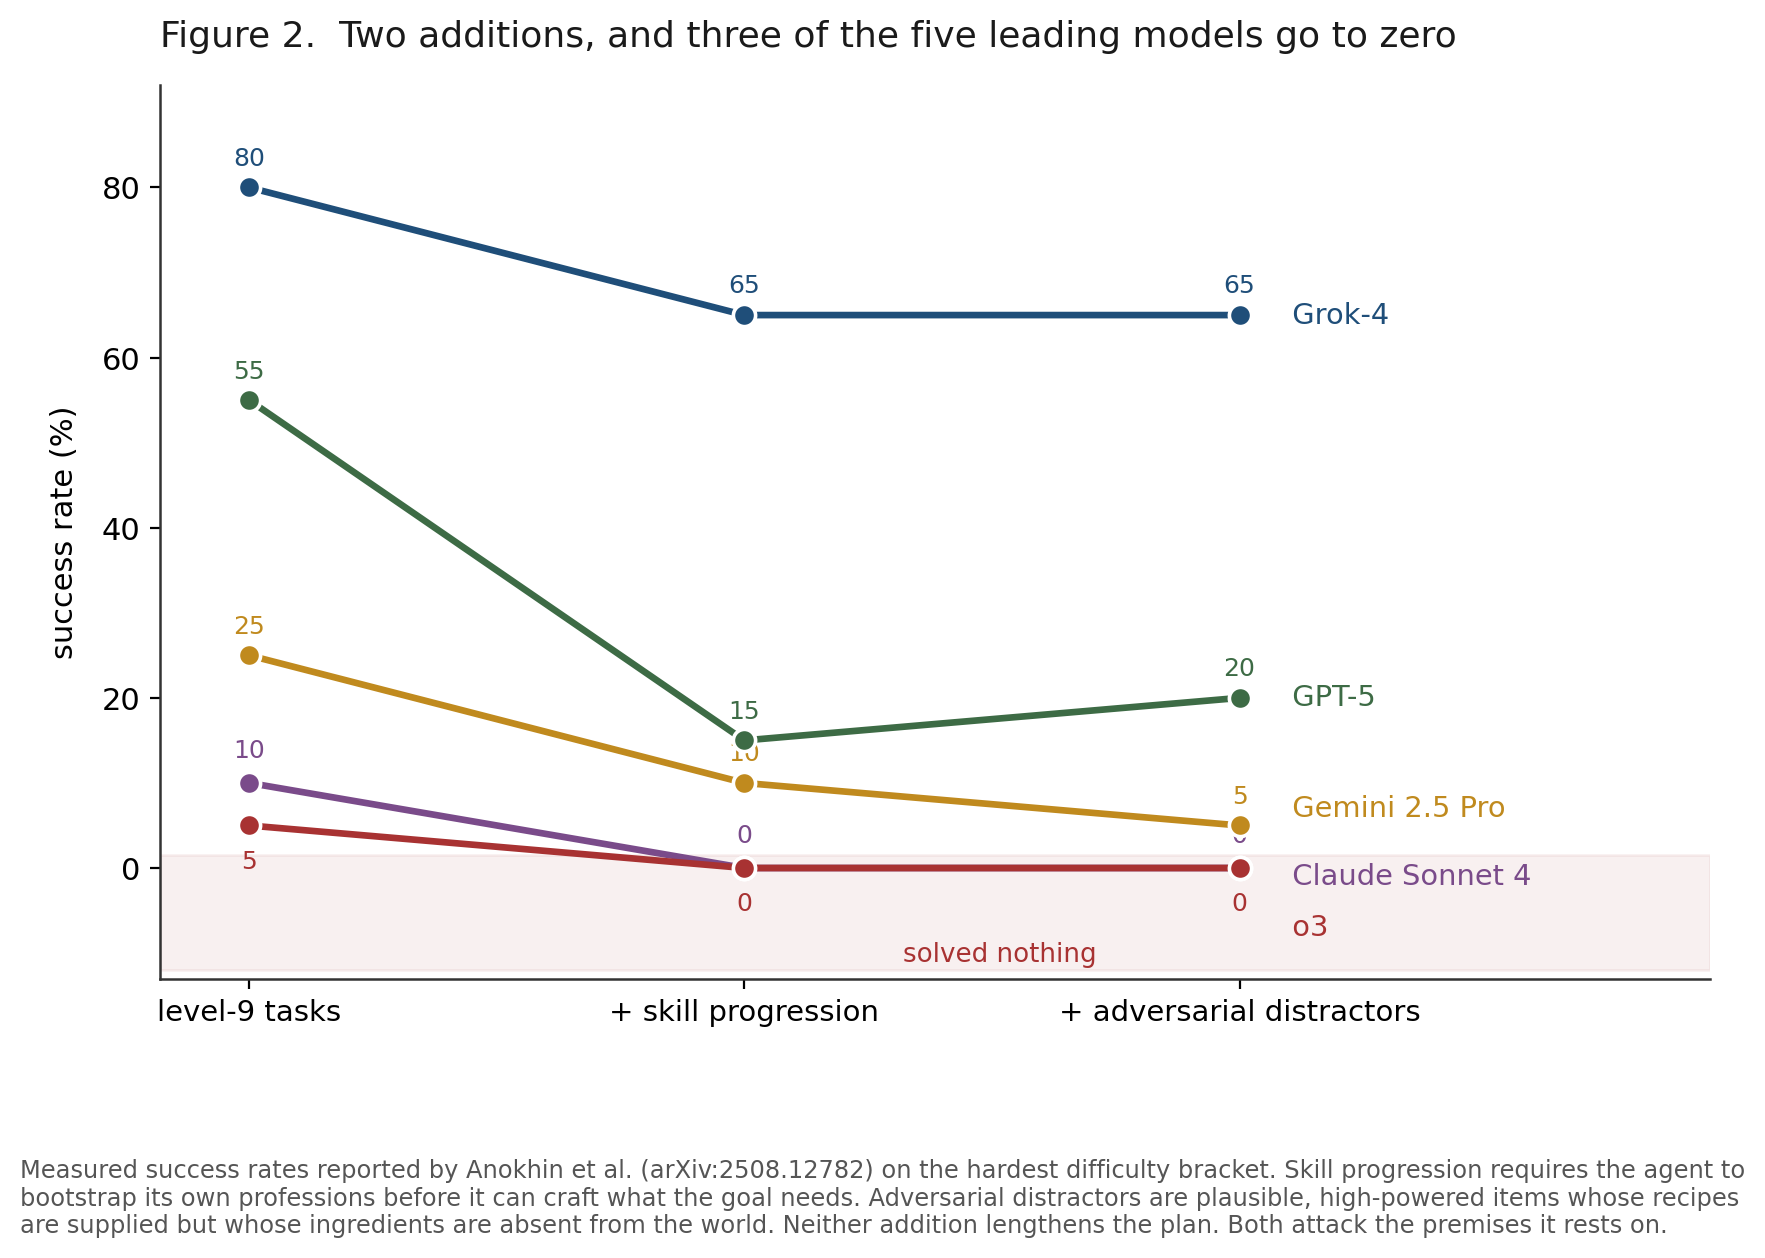
Figure 2. Two additions, and three of the five leading models go to zero. Success rates on the hardest difficulty bracket, before and after adding skill progression and adversarial distractors. Neither addition lengthens the plan. Both attack the premises it rests on.
Look at what happens. One model goes from 5% to nothing. Another from 10% to nothing. A third from 25% to 10% to 5%. The strongest holds at 65%, and the second-strongest drops from 55% to 15% and then recovers slightly to 20% — which is within the noise of twenty tasks and should not be read as robustness to distractors.
Now ask what these two modifications have in common. Skill progression adds a recursive dependency: to do X you must first be capable of X, and becoming capable is itself a planning problem. Distractors add a verification requirement: every candidate must be checked for constructibility before it is committed to, and a candidate that passes every surface filter fails only on a check nobody ran.
Neither is a length problem. Both are premise problems. The first says: your plan assumed a capability you do not have. The second says: your plan assumed an option that does not exist. And in both cases the agent will then generate a long, internally consistent, correctly executed sequence of actions in service of that assumption.
This is the same failure as the gear miscalculation, in two more forms. The agent is not bad at doing things. It is bad at checking that the things are doable.
VII. Search does not substitute for a better plan
The obvious remedy for an unreliable proposal is to sample it many times and keep the best. It is the remedy behind inference-time search, best-of-n, tree search over partial plans, and most of what gets described as “scaling test-time compute”.
The benchmark contains a clean test of it. On tasks at the easiest difficulty levels, a base model was given two hundred attempts and a reasoning-trained version of the same model was given ten.
At difficulty 1: the base model reached 45% across two hundred attempts, with a mean per-attempt success of 11.8%. The reasoning variant reached 65% in ten attempts, with a mean per-attempt success of 30.5%.
At difficulty 2 the gap is starker. The base model, two hundred attempts, reached 30% — and its mean per-attempt success was 0.6%. The reasoning variant, ten attempts, reached 75%, mean per-attempt 20.0%.
Twenty times the sampling budget, and it does not close the gap. The reason is structural and worth stating in general terms: sampling explores the support of the proposal distribution. If the correct plan is outside that support — if the model does not, on any draw, consider checking whether the distractor item is constructible — then no number of draws finds it. Search multiplies the chance of finding a good plan the model was already capable of proposing. It does not create capability.
There is a second reason, less often noticed. Search requires a verifier. If you draw two hundred plans, you need to know which one is right, and in a domain with a simulator you can just run them all. In a domain without one — a multi-day technical project, a legal strategy, a scientific programme — the thing that would rank the candidates is the thing you did not have in the first place. Search is cheap exactly where it is least needed.
VIII. Scaffolding is not free
The other standard remedy is architecture: decompose the task across specialised agents, add a critic, add experts, and let the structure do what the model cannot.
Two such systems were built and measured against a plain baseline. The first pairs a decomposer with a critic and performs two-level decomposition: a high-level plan, verified by the critic, then expanded into executable actions. The second is more elaborate — a curriculum agent forming high-level plans, an optional combat-analysis agent, map and crafting experts answering the decomposer’s queries, and a separate action agent producing the code.
The results, on the same underlying model:
At difficulty 2, the simple decomposer-critic pair reached 65%, the elaborate hierarchy 35%, and the bare baseline model 45%.
At difficulty 3, the simple pair reached 60%, the elaborate hierarchy 10%, and the baseline 15%.
The two-agent system helped substantially. The seven-agent system was worse than no system at all, and worse by a factor of six at the harder level. The stated diagnosis is prompt overengineering and context overload: the smaller models could not process what the subagents handed them, and hallucinated during plan and subtask generation.
Take the general lesson rather than the specific one. Every layer of scaffolding adds a boundary at which information must be summarised, passed, and re-interpreted, and every such boundary is a place where a premise can be silently altered. A critic that verifies a plan is one boundary and it earns its keep. A pipeline of experts producing summaries for a decomposer producing subtasks for an action agent is six boundaries, and if the model is not reliable enough to preserve meaning across them, the architecture is manufacturing exactly the failure mode it was built to prevent.
Architecture is not free reliability. It is a bet that the interfaces are cheaper than the problem, and the bet can lose.
IX. Thinking longer, and when it pays
One more result cuts against a comfortable assumption, and it concerns how much computation gets spent and by whom.
Reasoning-trained models beat their standard counterparts across every difficulty level. That much is unsurprising. What is surprising is the shape of the exception: the strongest non-reasoning model outperformed several open-source reasoning models, achieved a success rate close to one of the proprietary reasoning models, and beat it on progress score — while spending a fraction of the tokens. Measured as success per token spent, two non-reasoning models were the most efficient systems in the evaluation.
More telling is what happens as tasks get harder. Only two models substantially increased their reasoning length as difficulty rose. Everything else spent roughly the same computation on a task requiring five items as on one requiring ninety-seven — and those two models are the two that hold up at the top of the difficulty range.
That is adaptive computation, and its absence is a specific failure rather than a general inefficiency. A system that spends a fixed budget regardless of difficulty is not calibrated to the problem: it overspends on the easy tasks and underspends on the hard ones, and the underspending is where it loses. Note what it would take to fix: the system must estimate how hard the problem is before solving it, which is a judgement about its own uncertainty, and which is the same missing capability that shows up as overconfidence everywhere else.
There is a bound worth recording too. The strongest model solved the hardest tasks within twenty to thirty-five thousand output tokens. So these are not tasks that require unbounded deliberation; they are tasks that require the right deliberation. The gap between the model that solves them in thirty thousand tokens and the model that fails them in thirty thousand tokens is not a compute gap.
This matters for anyone reasoning about cost. The instinct is that long-horizon reliability will be bought with inference-time compute, and that the price will fall as compute gets cheaper. The measurement says the price is not being paid in compute by most of the systems that fail, because they never scaled their spending in the first place. What separates them is what they do with the budget, not the size of it.
X. What this measurement does not test
I have been leaning on one benchmark, and it is important to be exact about what it excludes — not to discount the findings, but because the exclusions are precisely the parts of the original problem that remain hardest.
There is no feedback. The plan is emitted whole and executed. The agent never observes an outcome and adjusts. So nothing here measures detecting that a plan has failed, deciding when to replan, or recovering from a surprise. Those are named as central difficulties in every serious statement of the problem, and they are switched off.
There is no stochasticity. Drop rates are set to certainty. The environment supports randomness and it was not used. So nothing here measures acting under uncertainty about outcomes, or maintaining a belief state over what has actually happened.
There is no partial observability. The agent is handed the world description — the dependency graph, the locations, the statistics — in the prompt. The formal difficulty of the original problem is that the agent does not observe the true state and must infer a belief state from incomplete observations. Here the state is given.
So this is a pure test of planning under complete information in a static world. That is a legitimate and clarifying thing to isolate, and it has an important consequence for reading the numbers: they are an upper bound. An agent that cannot construct a correct plan when told everything, in a world that will not move, is not going to do better when the information is partial and the world responds.
Three of five leading models scoring zero on the hardest configuration is therefore worse news than it looks, not better. It is the easy version.
XI. The seven difficulties, sorted
The standard list of what makes long-horizon planning hard is a mix of things that are established, things that are misdiagnosed, and things that are untested. Sorted against the evidence:
Compounding error. Real, and not the binding constraint at the top of the range. It dominates when execution is unreliable — the weak models in Figure 1 make several execution errors per task and fail everything. It stops mattering once execution error reaches a few hundredths per task, which it now does. What replaces it is not a smaller version of the same thing; it is a different thing.
Sparse reward and credit assignment. Real, and partly addressed by measurement design rather than by architecture. The benchmark’s progress score, which counts valid intermediate accomplishments, exists precisely because binary success discards the information needed to tell a near-miss from a catastrophe. The error attribution — was it gear, execution, both, or invalid code — is the same move at finer grain. Credit assignment is not only a training problem; it is first an evaluation problem, and you cannot solve the former without solving the latter.
Plans alter their environments, so premises expire. Real, and this is the skill-progression case: the agent’s own capabilities are part of the state, and the plan changes them. Notice that this is the failure that reduced two leading models to zero. The difficulty is not that the world changes unpredictably; it is that the agent must reason about a state its own plan will modify.
Branching factors grow exponentially, so search struggles. True in the abstract and misleading in practice, because the binding constraint is the proposal distribution, not the search budget. Two hundred samples from a weak proposer lose to ten from a strong one. Adding search to a system that is not proposing the right kind of plan does not help, and the verifier problem means search is least available where it would be most valuable.
Models generate convincing rationalisations rather than causally effective plans. This is the central finding, and Figure 1 is its measurement. The plans are not incoherent. They are coherent, well-formed, correctly executed and wrong at the root. Fluency in the plan is exactly as uninformative about correctness as fluency in an answer.
Skills learned separately do not compose in unseen combinations. Partly visible here in the skill-progression collapse, though the benchmark is not a clean test of it. What it does show is that a model can be reliable at each of gathering, crafting, combat calculation and code generation, and unreliable at the composition — which is the claim in a specific instance.
External memory records but does not guarantee retrieval, interpretation or update. Untested here, because the memory is the prompt. In the multi-agent results there is a shadow of it: the experts held knowledge, the decomposer had to query and interpret it, and the interpretation is where the elaborate system fell apart. That is a memory-interface failure in miniature.
XII. What a defensible claim looks like
If the failure is premises rather than steps, then the engineering follows, and it is not the engineering the compounding story recommends.
Verify the plan before executing it, not the steps while executing it. A checker that confirms every action is well-formed is checking the part that already works. A checker that confirms every item in the plan is actually constructible in this world, that the arithmetic on which the plan depends is correct, and that the prerequisites the plan assumes are either held or acquired within the plan — that is checking the part that fails. In the benchmark, both properties are mechanically checkable, and in most real domains at least some of them are.
State the premises as artefacts, not as prose. A plan should carry, separately from its actions, the list of propositions it depends on: this gear defeats that monster; this recipe is constructible; this profession will reach level twelve by step forty. Each is falsifiable before a single action is taken. A plan whose premises are buried in the narrative cannot be checked at the layer where it fails.
Declare invariants and check them during execution. Not “did the action succeed” but “is the thing that must remain true still true”. Resource counts, level requirements, the continued availability of a location. Invariant violation is the signal that a premise has expired, and it is the only cheap way to detect it before the end.
Report failure attribution, not success rate. A number that says 44% tells you nothing about what to fix. The decomposition — high-level plan versus execution versus formatting — is the reason this benchmark is more informative than a leaderboard, and it costs nothing but the discipline of instrumenting the evaluation. Any agent evaluation that reports a single success rate is discarding the information its own developers most need.
And state the conditions. Deterministic or stochastic. With feedback or single-shot. Full state or partial observation. These are not footnotes; they are the difference between an upper bound and a measurement. A system reported at 65% under complete information in a static world has told you nothing about its behaviour when the world moves.
None of that gets to multi-day autonomous technical work. It gets to something more modest and more useful: an agent whose failures are attributable, whose premises are inspectable, and whose reported reliability means something outside the conditions it was measured in.
XIII. What would show me wrong
If the planning-error gap closed — if a model reached the point where its high-level plan errors fell to the same order as its execution errors, and both were near zero — then the argument of this essay would become historical. The gap in Figure 1 is roughly five-to-one at the top and I have no principled reason to think it cannot narrow. It is checkable in an afternoon: rerun the error attribution and look.
If repeated sampling with a genuinely good verifier turned out to close the gap that reasoning training closes — if two hundred draws plus a strong checker matched ten draws from a better proposer — then Section VII is overstated, and the correct architecture is cheap generation plus expensive verification. The experiment reported here does not test that combination, because it compares sampling budgets rather than sampling-plus-verification against sampling alone.
And if the exclusions turn out to work in the other direction — if agents with feedback and the ability to replan do substantially better than the single-shot numbers, because a wrong premise gets caught by the environment rather than carried to the end — then the single-shot results are a lower bound rather than an upper one, and my reading of them is backwards. I do not think that is how it goes, because detecting that a plan has failed for premise reasons requires noticing that the failure was not local, which is the same competence that would have caught the premise. But it is an empirical question and the benchmark’s authors have the interactive mode built already.
XIV. Coda
The compounding story is attractive because it is arithmetic, and arithmetic feels like proof. But pⁿ is a model, and a model with two assumptions in it, and both of them fail for the systems in question. Steps are generated by structure, so there are far fewer decisions than actions. Errors are correlated, so they arrive in clusters traceable to a source rather than sprinkled along the sequence.
What the measurements show is a system that has become very good at doing and remains unreliable at deciding what to do. Execution is nearly solved. The equipment calculation that determines whether the whole plan can work is not. Add a prerequisite the agent must bootstrap, or an option that looks right and cannot be built, and most of the leading models go to zero — on tasks where they are told everything and the world holds still.
The useful agent is not the one that takes a thousand actions without a slip. It is the one that establishes, before it takes any, that the thousand actions can possibly work — and that says so when it cannot.
References
Anokhin, P., Khalikov, R., Rebrikov, S., Volkov, V., Sorokin, A., & Bissonnette, V. (2025). HeroBench: A Benchmark for Long-Horizon Planning and Structured Reasoning in Virtual Worlds. arXiv:2508.12782